MCP-RagMax ทำงานอย่างไร — Hybrid Retrieval, Build Jobs และ Orientation Index
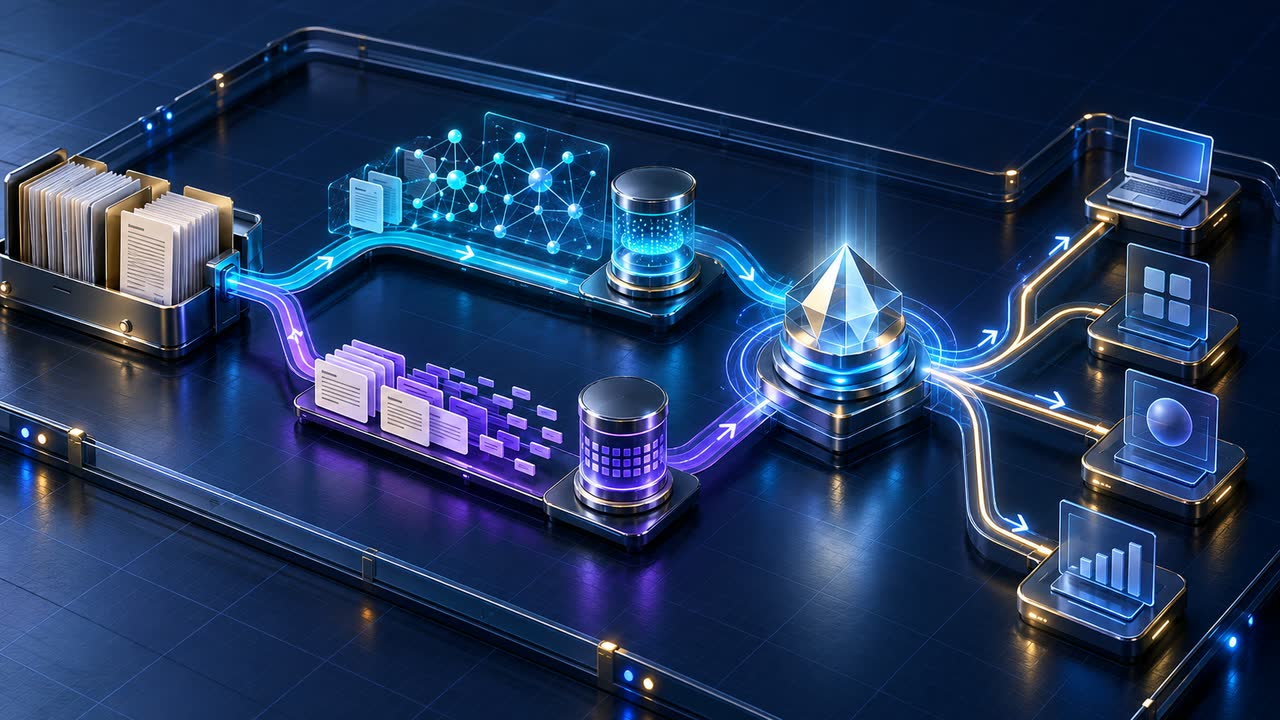
MCP-RagMax แยก retrieval backend ออกจาก agent ที่คิดและตอบผู้ใช้ อย่างชัดเจน ตัว backend ไม่เรียก LLM เพื่อค้น, rerank, ตัดสิน build หรือเขียน metadata ทำให้ผลลัพธ์ส่วนแกนกลางตรวจสอบซ้ำได้และไม่ขึ้นกับ mood ของโมเดล
ภาพรวม
workspace/knowledge/
      │
      ▼
extract + chunk + registry
      │
      ├──► MiniLM dense index
      └──► Thai-aware BM25
                 │
                 ▼
              RRF fusion
                 │
                 ▼
      deterministic parent selection
                 │
      ┌──────────┴──────────┐
      ▼                     ▼
 MCP stdio 9 tools      HTML console :8770
Source file กับ derived state ถูกแยกคนละที่: เอกสารต้นฉบับอยู่ใต้ workspace/knowledge/ ส่วน registry, Chroma/BM25, build jobs และ rag_index.json อยู่ใต้ workspace/.rag_state/
1. Hybrid Retrieval: Dense + BM25 + RRF
rag_retrieve ค้นด้วยสองมุมพร้อมกัน:
- Dense search ใช้
sentence-transformers/paraphrase-multilingual-MiniLM-L12-v2เพื่อจับความหมายข้ามภาษาและคำที่ไม่ตรงตัว - BM25 ใช้ lexical matching ที่ตัดคำไทยเพื่อเก็บความแม่นจากคำจริงในเอกสาร
ผลจากทั้งสองทางถูกรวมด้วย Reciprocal Rank Fusion (RRF) แทนการเอาคะแนนคนละสเกลมาบวกตรงๆ จากนั้น backend เลือก parent context แบบ deterministic และตัดซ้ำก่อนคืนให้ caller
Caller ส่ง query variants ได้ แต่ variants ต้องเป็นคำถามเดิมคนละรูป ไม่ใช่การเพิ่ม subquestion ใหม่ Backend จะค้นแต่ละ variant แยกแล้ว fuse ผลรวมอีกที
2. Registry เป็นขอบเขตความจริงของไฟล์
MCP-RagMax ไม่เปิด arbitrary filesystem read ไฟล์ที่จะถูก list/search/read ต้องถูก register ผ่าน knowledge-base lifecycle ก่อน
rag_listแสดง registered filesrag_search_filesค้นชื่อใน registryrag_read_fileอ่านได้เฉพาะ registered file- UI reveal ไป Finder ก็ resolve ผ่าน registered path เหมือนกัน
จุดนี้ทำให้ knowledge root เป็น capability boundary ไม่ใช่แค่ convention
3. Incremental Build และ deterministic dedup
build_kb สแกน source root แล้ว process เฉพาะไฟล์ใหม่หรือเปลี่ยนแปลง มี exact-hash dedup และ semantic duplicate rejection ที่ deterministic ก่อน publish state ใหม่
Registry, Chroma และ BM25 มี consistency/rollback guards เพื่อไม่ให้ derived stores หลุดจากกันง่ายๆ
4. Persistent background jobs
การ build ผ่าน MCP ไม่บล็อก agent ยาวๆ:
build_kb()
  → job_id
  → build_status(job_id)
  → running / progress / ETA
  → completed | cancelled | failed
Job state อยู่ใต้ workspace/.rag_state/build_jobs/ จึงยัง poll ต่อได้แม้ stdio MCP process เดิมจบไปแล้ว
Cancellation ไม่ลบข้อมูลกลางคันแบบเสี่ยง
- ไฟล์ใหม่: ถ้ายกเลิกกลาง ingest สามารถ rollback partial writes
- ไฟล์ที่เปลี่ยน: เมื่อเข้าช่วง replace old rows แล้ว จะทำไฟล์ปัจจุบันให้จบก่อน honoring cancellation เพื่อไม่ปล่อย source นั้นหายจาก index
นี่คือเหตุผลที่ cancel_build เป็น cooperative cancellation ไม่ใช่ kill process ทันที
5. rag_index.json: ให้ LLM ช่วยเฉพาะสิ่งที่ควรช่วย
Orientation index ต้องการ topic labels ที่มนุษย์อ่านง่าย แต่ไม่ควรปล่อยให้ LLM แต่ง counts/tags/source types ตามใจ MCP-RagMax จึงใช้ two-phase protocol:
prepare
  → deterministic snapshot
  → expected_fingerprint
  → caller LLM เสนอ topics 1–30 รายการ
commit(topics, expected_fingerprint)
  → validate topics
  → recompute backend metadata
  → recheck fingerprint
  → atomic install
LLM ช่วยเฉพาะ semantic labeling ส่วนข้อเท็จจริงเชิงโครงสร้างยังมาจาก backend
ถ้า KB เปลี่ยนระหว่างสอง phase fingerprint จะไม่ตรงและ commit ถูกปฏิเสธ
6. Health ไม่ได้เช็คแค่ว่า process ยังอยู่
rag_health ใช้ตรวจหลายชั้น เช่น Chroma/BM25/registry consistency, pipeline fingerprint, orientation index และสถานะ job เพื่อให้ caller รู้ว่า retrieval พร้อมจริงหรือมี derived state ส่วนไหนต้องซ่อม
7. Local HTML console ใช้ core เดียวกับ MCP
web_ui.py bind เฉพาะ loopback และเรียก deterministic RAG core ชุดเดียวกัน ไม่ได้มี retrieval engine อีกตัว หน้าเว็บใช้สำหรับ:
- Search
- Health
- Files
- Build / progress / cancel
- prepare / commit
rag_index.json - reveal registered source ใน Finder บน macOS
State-changing request มี same-origin check และ Finder reveal ปฏิเสธ path ที่ไม่อยู่ใน registry
ทำไมแยก backend ออกจาก agent
การแยกนี้ทำให้ agent ตัวเดียวกันเปลี่ยนได้โดยไม่ต้อง rebuild knowledge architecture และหลาย agent สามารถใช้ KB เดียวกันผ่าน contract เดียวกันได้
Agent A ─┐
Agent B ─┼── MCP ──► MCP-RagMax
Agent C ─┘
แต่ละ agent ใช้ LLM ของตัวเองเพื่อวางแผน/สรุป ขณะที่ retrieval และ source boundary ยังคงเหมือนเดิม
ความคิดเห็น
กำลังโหลดความคิดเห็น...